How Privacy Teams Protect PII in Process Analytics With a 9 Step Plan
Yes, PII commonly appears in process analytics event data, hiding in case attributes, free-text fields, and timestamps that nobody flagged during ingestion. The re-identification risk is real once you combine a few innocuous fields. Start by locating and blocking raw identifiers at the source, then apply masking, pseudonymization, or differential privacy before the data reaches your process mining tools, depending on how sensitive the fields are and how much analytic precision you need to keep.
TL;DR:
- Combining seemingly innocuous fields like timestamps, case IDs, or department codes can uniquely identify individuals and pose re-identification risks.
- Most leaks happen through unstructured free-text notes or third-party SDKs that append device identifiers or IP addresses without proper oversight.
- Differential privacy, partitioning, and cryptographic methods can mitigate re-identification risk but require precise inventory and risk assessment first.
- Teams should prioritize discovering all data flows with automated scans and-process mining tools, then apply risk-based remediation strategies systematically.
- Legal and governance policies must define acceptable privacy thresholds upfront, with clear documentation for auditability and ongoing monitoring.
Table of Contents
- What counts as PII in process analytics: concrete examples and borderline cases
- Where PII hides in event logs and analytics pipelines
- Technical controls and privacy-preserving techniques you can apply
- Governance and compliance: policies, vendor risk and legal considerations
- Step-by-step operational workflow to discover, classify and remediate PII
- Patterns Process Finder: enterprise-grade discovery with privacy-conscious capture
- Why most PII advice for process analytics misses the point
- Sources
- FAQ
What counts as PII in process analytics: concrete examples and borderline cases
Names, email addresses, Social Security numbers, and personal phone numbers are unambiguous PII in any event log. So is precise location data. Google’s analytics guidance treats fine-grained location, anything more precise than about one square mile, the same way it treats an explicit name field: as data you should never send into an analytics platform in the first place.
Process analytics has its own flavour of this problem, though, because the risky fields rarely announce themselves. A “resource” attribute in an event log might read as an employee ID, but if that ID maps one-to-one with a badge number or an email prefix, it is functionally a name. Full timestamps down to the second, when paired with a case ID and a location, can pinpoint an individual employee’s shift pattern well enough to identify them without a single explicit name field appearing anywhere in the log.
The borderline cases are where most teams get sloppy:
- IP addresses are PII in most jurisdictions when tied to an identifiable person or device, even though they look like network metadata.
- Advertising IDs and cookies sit in a grey zone. Google’s own guidance distinguishes them from explicit identifiers, but they still function as persistent identifiers when combined with behavioural data.
- Hashed identifiers feel safe, but an unsalted hash of a common field (an email, an employee number) is often reversible through a straightforward dictionary attack.
- Free-text fields (support ticket notes, form comments, exception reasons) are the least monitored and most likely to contain a name, a phone number, or an address typed in by a human who did not think about analytics downstream.
The composite risk matters more than any single field. A case ID, a department code, a shift start time, and a resolution timestamp, none of them PII on their own, can uniquely identify one employee out of a team of twelve. Threat research on process mining confirms that privacy risk in event logs is rarely about one bad column. It is about the combination.
Where PII hides in event logs and analytics pipelines
Most teams scan the obvious fields (name, email) and call the job done. The actual leakage tends to sit in five places, and scanning them in the wrong order wastes weeks of audit time.
- Event attributes and custom fields. Case IDs, resource names, and any custom attribute added by a business unit are the first place to look. Free-text notes attached to exceptions or manual overrides are the worst offenders because they were never designed with a schema.
- URLs, referrers, and query parameters. Web-derived event logs frequently carry session tokens, email addresses, or account numbers directly in the query string. Google’s own guidance on avoiding PII in Analytics specifically warns against passing identifiers through URLs, page titles, or custom dimensions, and recommends sanitizing at the point of capture rather than after ingestion.
- Timestamps and location, treated as indirect identifiers. A second-level timestamp is rarely a problem alone. Paired with a small population (a single team, a single shift), it becomes a fingerprint.
- Third-party enrichers and SDKs. Marketing tags, session replay tools, and analytics SDKs sometimes append device fingerprints, IP addresses, or user agent strings to your event stream without anyone on the analytics team requesting it. These exports often bypass your own data governance review entirely, because they happen inside a vendor’s black box.
- Legacy exports and manual joins. The riskiest PII exposure usually happens when someone joins an anonymized event log back against an HR roster “just to check something,” and that joined file ends up on a shared drive.
Prioritizing your scans means starting with free-text fields and third-party SDK exports first, since those two sources account for the majority of unplanned PII leakage in analytics pipelines. Structured fields with a known schema are comparatively easy to audit; unstructured ones are where surprises live.
For discovery methods, four techniques cover most of the ground:
- Sampling a few thousand rows manually catches obvious issues fast and cheaply, before you invest in tooling.
- Regex and dictionary scans catch structured patterns (SSN formats, email formats, phone number formats) at scale.
- Entropy and anomaly detection flag fields with unusually high cardinality or unexpected character distributions, which often signal a leaked identifier hiding inside a field that was supposed to be categorical.
- Lightweight ML classifiers trained on labelled examples generalize better than regex alone, especially for free-text fields where PII does not follow a fixed pattern.
Pro Tip: Run your entropy detector against every “free text” or “notes” column before you run it against structured fields. Unstructured columns produce PII leaks at a much higher rate than structured ones, and they are the columns most compliance scans skip entirely because nobody expects a name to show up in a “comments” box.
Automated discovery tools can shorten this scanning phase considerably by producing an accurate inventory of what data actually flows through a process, rather than relying on documentation that describes an idealized version of the workflow. A process mining tool built for this purpose reduces the manual auditing burden that otherwise falls entirely on privacy teams working from stale system diagrams.
Technical controls and privacy-preserving techniques you can apply
Once you know where the PII lives, the engineering choice comes down to how much re-identification risk you can tolerate against how much analytic precision you need to keep. There is no single correct answer here. The right technique depends on whether you are protecting a directly-follows graph, a frequency count, or a raw event stream headed for a data lake.
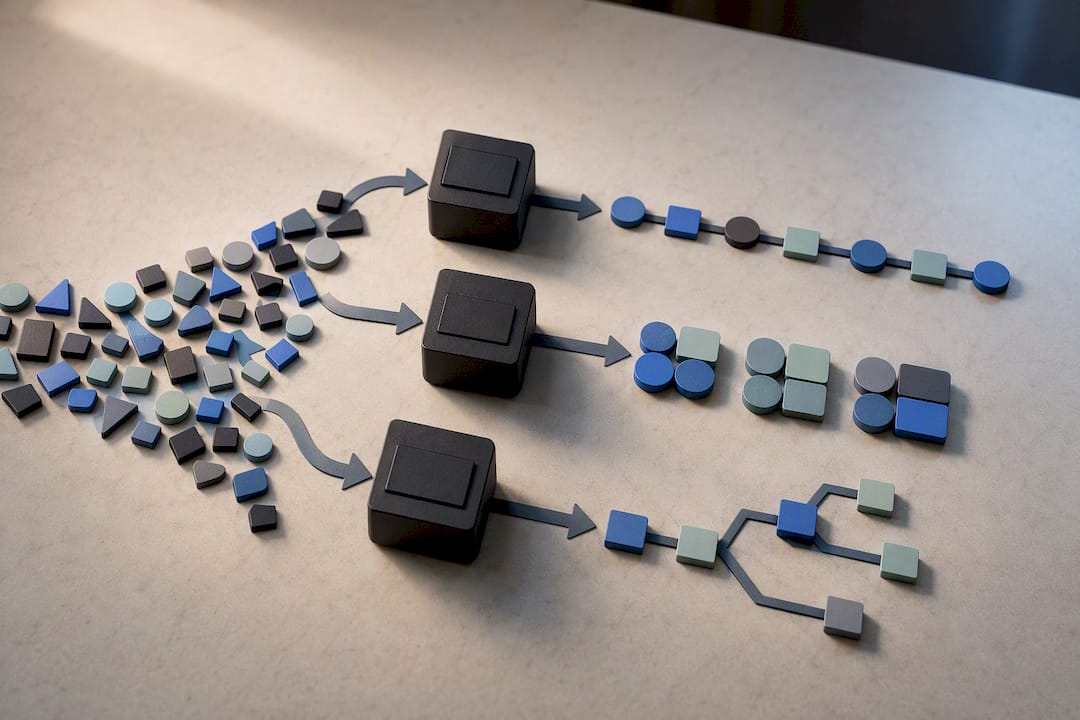
Pseudonymization and hashing replace an identifier with a token or a hash, keeping the field usable for joins without exposing the original value. The catch is linkage risk: an unsalted hash of a common field is reversible through a dictionary attack in minutes. Salting each hash and rotating the salt periodically closes that gap, but rotation breaks longitudinal joins unless you maintain a secure mapping table, which becomes its own compliance liability if it is ever exposed.
Anonymization models like k-anonymity, l-diversity, and t-closeness generalize or suppress values until any individual is indistinguishable from at least k others in the dataset. These models work well on small, low-dimensional tables. Event logs are neither. Research on process mining privacy notes that finding an optimal k-anonymization becomes NP-hard once you are dealing with the high-dimensional, high-cardinality structure typical of a real event log with dozens of attributes per case. That is why most process mining teams now lean on differential privacy or partitioned anonymization instead of trying to force k-anonymity onto a full log.
Differential privacy (DP) adds calibrated statistical noise to outputs like directly-follows graphs (DFGs) or activity frequency counts, so that no single case’s presence or absence materially changes the result. The privacy parameter, epsilon, controls the trade-off: a smaller epsilon means stronger privacy and more noise; a larger epsilon means better utility and weaker guarantees. Choosing epsilon in the abstract is nearly meaningless to a compliance officer, which is why the more useful framing translates it into business terms.
Statistic callout: One framework for balancing DP risk and utility in directly-follows graphs works backwards from an acceptable business risk. Teams first compute the attacker’s prior guessing probability, set a maximum allowable “guessing advantage” the noise must suppress it below, then solve for the epsilon value that satisfies that constraint while tracking the expected absolute percentage error (APE) the added noise introduces into the DFG. This approach replaces guesswork about choosing epsilon with a documented, defensible calculation tied to a stated risk tolerance.
That same research found that partitioning event logs into meaningful sub-processes before anonymizing them consistently improves precision over anonymizing the full log at once. Splitting a log by department, product line, or process variant before you apply DP noise means each partition needs less aggressive noise to hit the same privacy guarantee, because the population within each partition is more homogeneous. A partitioning study on privacy-aware process discovery measured meaningfully higher F1 scores for discovered process models when anonymization ran per sub-log rather than globally, a pattern worth building into your remediation playbook rather than treating as a one-off optimization.
Newer algorithm families designed specifically for process mining, including SaCoFa, SaPa, and the PRETSA line, try to preserve control-flow semantics while still meeting a formal privacy guarantee, rather than just injecting uniform noise everywhere. Research comparing these techniques shows they retain more of the underlying process structure than naive noise insertion, which matters if your downstream goal is conformance checking or bottleneck analysis rather than just headline metrics.
Cryptographic approaches solve a different problem: discovery on encrypted data without ever decrypting it centrally. Homomorphic encryption and deterministic encryption schemes underpin emerging Process-Mining-as-a-Service (PMaaS) designs, letting a third party run discovery algorithms against encrypted logs. Some of these designs report no measurable utility loss compared to running the same discovery on plaintext, which makes them attractive for organizations that cannot legally centralize raw event data at all, such as multi-tenant environments with strict data residency requirements.
Tooling matters here more than most teams expect. PM4Py, the widely used open-source process mining library, has integrated differential privacy and anonymization algorithms directly into its pipeline, so teams no longer need to bolt privacy processing on as a separate, error-prone step before import. PRIPEL and related anonymization libraries extend that further, offering event-log-specific noise injection that respects control-flow structure rather than treating the log as a generic tabular dataset. Deployment notes worth keeping in mind:
- Run anonymization as a documented pipeline step with version control, not a manual script someone runs before a demo.
- Log the epsilon (or k, l, t parameter) used for every export, so audits can reconstruct exactly what privacy guarantee applied to which dataset.
- Test utility loss on your actual downstream metrics (fitness, precision, MAPE) rather than trusting a vendor’s generic benchmark, since utility loss varies significantly by log structure.
Governance and compliance: policies, vendor risk and legal considerations
Technical controls only work if governance defines what “acceptable risk” actually means before an engineer has to guess. Harvard Business School’s research on data privacy makes the point plainly: privacy gets treated as an afterthought in most organizations, bolted onto a project after the data model is already built. Process analytics teams should flip that order, deciding acceptable-risk thresholds during the design phase, not during the post-incident review.
That starts with a written, board-approved definition of acceptable risk, expressed in terms a non-technical stakeholder can evaluate. “Epsilon equals 0.5” means nothing to a general counsel. “An attacker’s chance of correctly identifying an individual employee’s activity rises by no more than 5 percentage points over a blind guess” means something concrete they can approve or reject.
Legal counsel needs to be looped in earlier than most analytics teams assume, particularly for ambiguous cases: employee monitoring data, contractor activity logs, and any process log that touches customer-facing case files. Whether a given field counts as PII under a relevant regulation is a legal determination, not a technical one, and the definitions shift across jurisdictions. A structured method like PCRE gives legal and technical stakeholders a shared seven-phase process for assessing confidentiality, decomposing composite fields into their component identifiers, and documenting the mitigation each field requires, so the decision trail survives an audit two years later.
Consent and lawful basis deserve explicit attention when the data being analyzed comes from employee activity monitoring rather than customer interactions. Employees rarely have meaningful consent leverage over workplace monitoring, which shifts the compliance burden toward transparency notices, data minimization, and a documented legitimate business interest rather than consent alone.
Governance artifacts worth building before your first production pipeline, not after an incident:
- A privacy risk register listing every known PII source, its current remediation status, and the owner accountable for it.
- A data minimization checklist applied at ingestion, confirming that every collected field has a stated analytic purpose.
- A remediation playbook mapping risk tiers to specific technical responses (masking, DP, tokenization) so responses are consistent across teams.
- Vendor data processing addenda for every third-party SDK or enrichment service touching your event stream, with audit rights written in, not assumed.
- Access controls and audit logging covering who queried raw versus anonymized data, when, and why, retained long enough to satisfy your regulator’s lookback period.
On the access control side, treat role-based permissions as a first-class control, not a checkbox. Analysts working on aggregate throughput metrics rarely need row-level access to raw case data; give them the anonymized or partitioned view by default, and require a documented exception request for raw access. A practical reference point for this comes from privileged access management practices built for exactly this kind of tiered, audit-friendly permission structure. Vendor risk deserves the same scrutiny: a data processing addendum that does not specify what the vendor’s SDK collects, retains, or re-exports is not worth much when an auditor asks you to prove what left your environment.
Step-by-step operational workflow to discover, classify and remediate PII
This workflow assumes you are starting from an existing process analytics pipeline that has never had a formal privacy review, which describes most organizations honestly.
- Scope the analytic goal before touching the data. Decide what the analysis actually needs to answer (bottleneck detection, conformance checking, throughput forecasting) so remediation choices preserve the utility that matters instead of anonymizing everything uniformly.
- Inventory every source and export path. Map ingestion points, third-party SDKs, and every downstream export, including scheduled reports and ad-hoc data pulls analysts run manually.
- Run automated scans across the inventory. Combine regex and dictionary matching for structured fields with entropy detection and ML classifiers for free-text fields, then validate a sample manually to catch what the automated pass missed.
- Score each identified risk against a documented threshold. Tie the scoring to the guessing-advantage framework described earlier, so a “high risk” label maps to a specific, defensible number rather than a gut feeling.
- Remediate by risk tier, not uniformly. Low-risk fields might only need pseudonymization; medium-risk aggregate outputs might need DP noise calibrated to your chosen epsilon; high-risk raw exports might need to stop entirely until a cryptographic or tokenization solution is in place.
- Partition before you anonymize wherever the log structure allows it. Splitting by process variant or business unit before applying DP noise consistently preserves more analytic signal than anonymizing the full log at once, based on the partitioning research cited earlier.
- Validate utility loss on your real metrics. Measure fitness, precision, and MAPE against your pre-remediation baseline, not against a generic benchmark, because utility loss varies by log structure and by how skewed your case volumes are.
- Document every decision for audit. Record the epsilon or anonymization parameter used, the risk score it was chosen to satisfy, and who signed off, tied back to your privacy risk register.
- Operationalize monitoring, not a one-time fix. Set alerts for schema drift (a new field appearing in the event stream), re-run your scans on a fixed cadence, and re-evaluate risk thresholds whenever the underlying process or its stakeholder population changes materially.
Pro Tip: Treat step six, partitioning before anonymizing, as your default rather than an edge case. Teams that anonymize the full log first and only partition afterward usually end up injecting far more noise than the analysis needed, because the noise calculation had to account for the full population’s variance instead of each partition’s narrower one.
Ongoing monitoring matters more than the initial cleanup, because pipelines drift. A new custom attribute added by a business unit six months from now can reintroduce exactly the PII exposure you just spent a quarter fixing. Building anonymization monitoring into your operational checks catches that drift before it becomes a quarterly audit finding instead of a same-week fix.
Patterns Process Finder: enterprise-grade discovery with privacy-conscious capture
The hardest part of any PII remediation program is not choosing between differential privacy and tokenization. It is building an accurate inventory of what data actually flows through your processes in the first place, because most organizations are working from documentation that describes how work is supposed to happen rather than how it actually happens.
A process discovery tool can capture real workflow executions across desktop and browser applications, producing traces and inventories that privacy and analytics teams need to understand which fields, systems, and subprocess branches are handling sensitive data. That distinction matters for PII remediation specifically: a hidden subprocess variation, a client-specific exception rule, or a manual workaround an employee developed independently often carries data through a path that no architecture diagram ever documented, which means it never made it onto anyone’s PII risk register either.
When discovery is built on privacy-conscious capture modes and enterprise security integrations, the inventory produced can help reduce the risk of raw identifiers leaking through undocumented data flows. Such a capture layer can feed directly into an anonymization or pre-processing pipeline: knowing where a field originates and every system it touches downstream makes applying masking, tokenization, or DP noise more precise than guessing based on incomplete documentation.
The practical benefits for a privacy-aware analytics program:
- Accurate, continuously updated inventories replace static documentation that goes stale the moment a team changes its workaround.
- Hidden subprocess and exception discovery surfaces the undocumented paths where PII most often slips through unmonitored.
- Privacy-conscious behaviour tracking supports capture without exposing raw identifiers unnecessarily during the discovery phase itself.
- Enterprise security protocol integration aligns discovery data collection with existing access control and audit requirements rather than working around them.
- Continuously updated SOPs give compliance teams a living reference for where sensitive data flows today, not where it flowed at last year’s audit.
Teams evaluating this approach can review Basic, Pro, and Enterprise plans to find the deployment scale that matches their pipeline complexity, or start with a pilot focused specifically on mapping the systems most likely to carry undocumented PII flows.
Why most PII advice for process analytics misses the point
Most guidance on this topic treats PII protection as a compliance checkbox: find the names, mask the names, move on. That framing misses where the actual risk lives. The composite re-identification problem, where a timestamp, a case ID, and a department code together identify someone that no single field would expose, is a structural property of event logs, not a data entry mistake you can fix with a better regex.
The conventional advice also overweights anonymization models like k-anonymity that were built for small, flat tables, and underweights the partitioning research showing that splitting logs before applying differential privacy preserves meaningfully more analytic utility than treating the whole log uniformly. Teams that skip partitioning are not being more careful. They are usually just adding more noise than the problem required.
If there is one priority to take from this, it is sequencing: build the inventory before you build the noise model. You cannot calibrate epsilon, choose a masking strategy, or write a defensible risk register for data you have not actually located yet. Discovery comes first. Everything else is a parameter choice.
— Malek
This article is general information, not a substitute for advice from a qualified lawyer. Consult a qualified legal professional about your own circumstances before acting on anything here.
Sources
The technical and regulatory claims in this article draw on a mix of vendor guidance, peer-reviewed process mining research, and open-source tooling documentation. Readers digging deeper should start here:
- Privacy and confidentiality in process mining - threats and research challenges
- Privacy-preserving process mining with PM4Py (extended abstract)
FAQ
What Are Some Examples of PII in Process Analytics?
Full names, email addresses, Social Security numbers, personal phone numbers, and precise location data are all explicit PII, and Google’s analytics guidance flags them directly. In event logs specifically, resource IDs tied to individual employees, free-text exception notes, and combinations of case ID, timestamp, and department code also carry real re-identification risk even though none of them looks like PII individually.
What Does PII Stand For in Data Governance?
PII stands for Personally Identifiable Information, meaning any data that can identify a specific individual either on its own or in combination with other available data. In data governance, the definition extends beyond obvious fields like names to include composite identifiers, which is why process analytics teams need to assess field combinations, not just individual columns.
What Information Is Not Considered PII?
Aggregate statistics that cannot be traced back to an individual, properly anonymized data that has passed a formal privacy assessment, and generic categorical fields (a department name shared by hundreds of employees, for example) generally fall outside PII definitions. Context still matters: a field that is not PII in isolation, like a broad location or a job title, can become PII once combined with other identifying attributes in the same log.
How Does GDPR Define and Regulate PII?
GDPR uses the broader term “personal data” rather than PII, and it defines that as any information relating to an identified or identifiable natural person, a standard that covers pseudonymized data if it can still be linked back to an individual. For process analytics teams, this means pseudonymization alone does not automatically satisfy GDPR; the data still counts as personal data unless it has been anonymized to the point where re-identification is no longer reasonably possible, which is why legal counsel should review ambiguous cases rather than leaving the call to engineering alone.